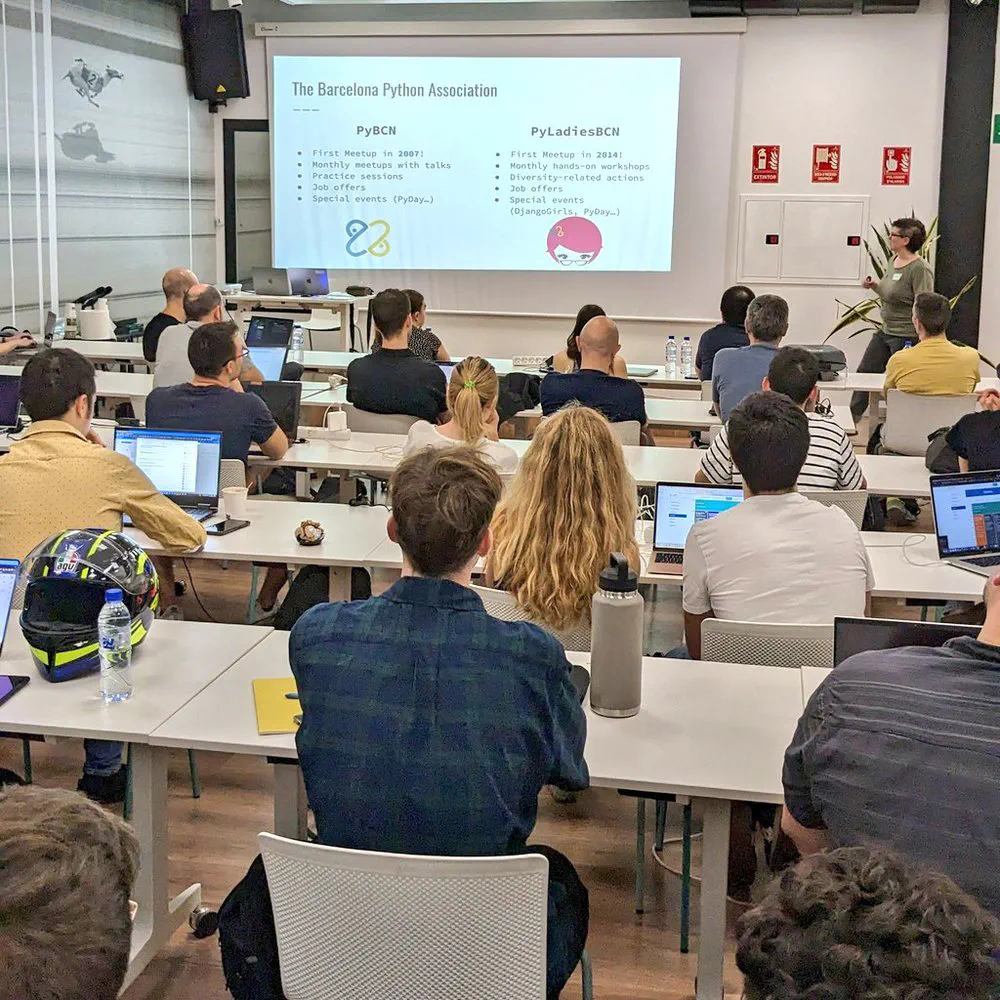
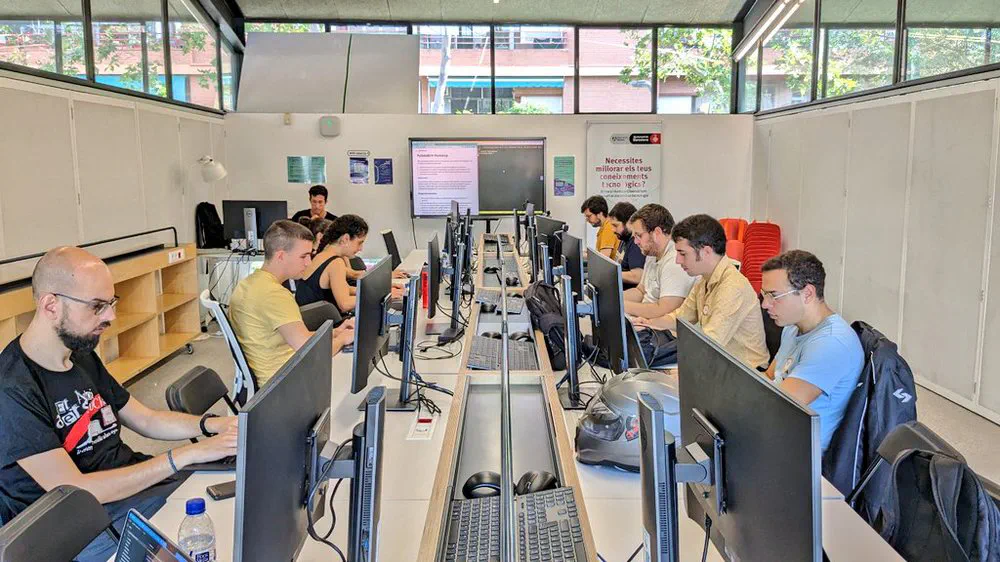
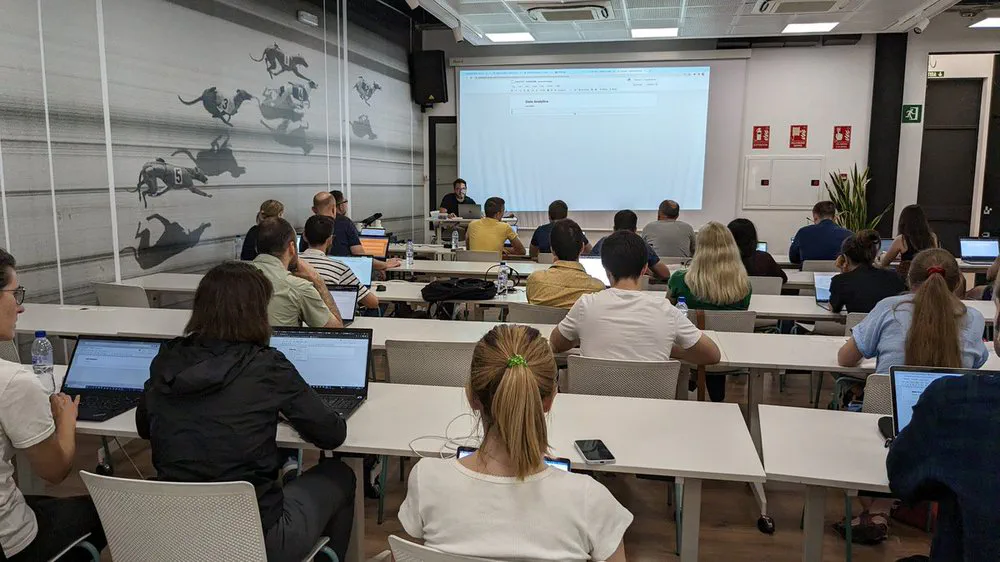
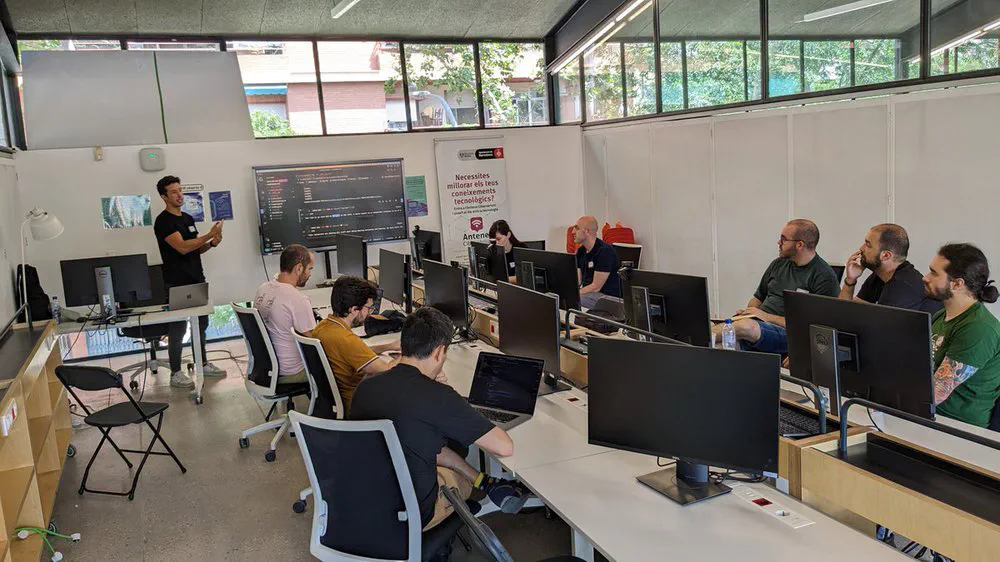
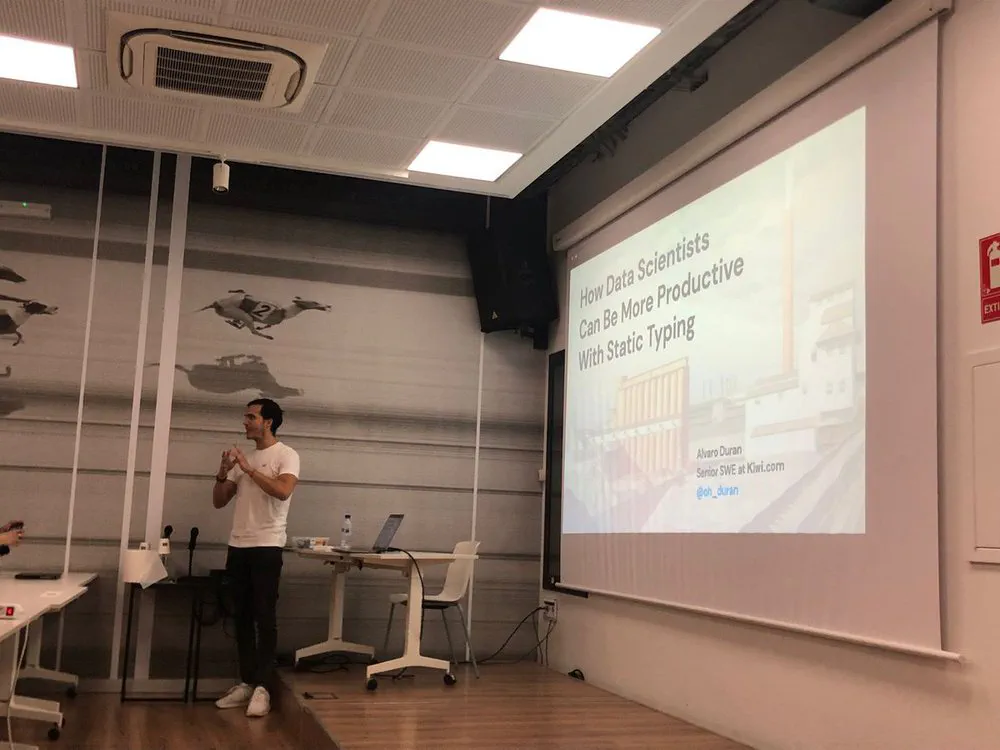
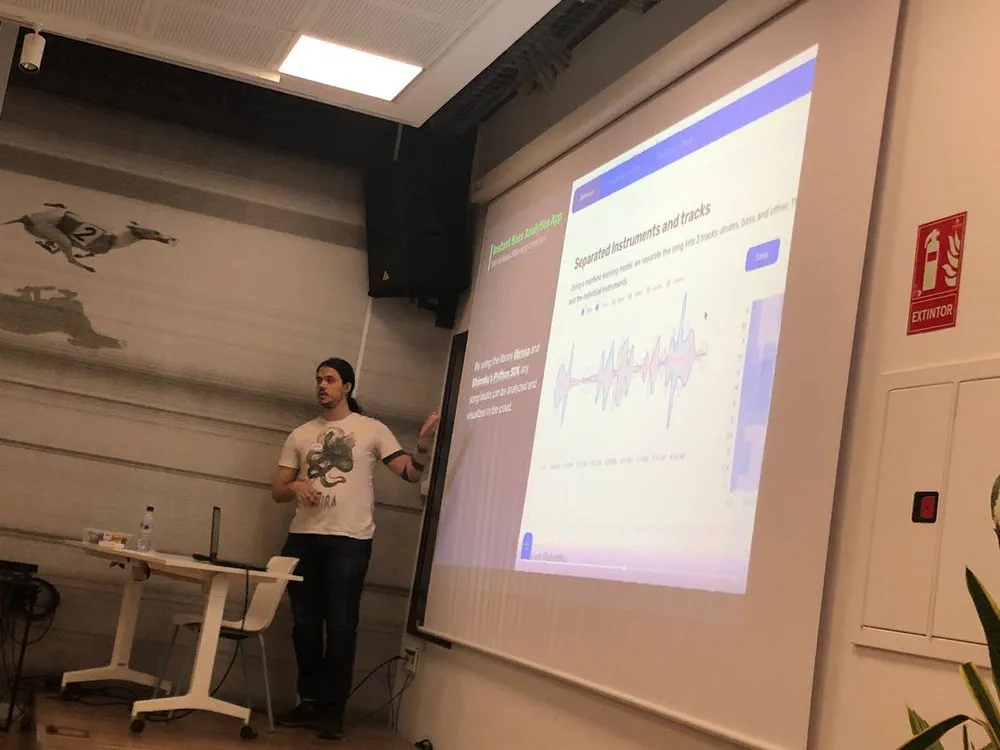
We are thrilled to announce the creation of PyDataBCN, our new annual event dedicated to bringing together the Data Engineering and Data Science community working with Python in Barcelona. PyDataBCN aims to provide a platform for knowledge-sharing, networking, and learning for professionals, enthusiasts, and students alike.
PyDataBCN will offer free hands-on workshops, lightning talks, and lots of fun activities. The workshops will be conducted by community members and will cover a range of topics related to data science, data engineering, machine learning, artificial intelligence, and more. Attendees will have the opportunity to learn new skills, get insights into the latest trends and best practices, and interact with like-minded individuals. The lightning talks will feature short and impactful presentations by speakers from academia and industry, who will share their experiences, insights, and perspectives on various topics related to data science and engineering. These talks will be followed by Q&A sessions, where attendees can ask questions and engage with the speakers.
In addition to the workshops and lightning talks, PyDataBCN will also host various fun activities, including networking events, Kahoot games, and more. We believe that learning should be enjoyable and that attendees should have the opportunity to connect and engage with each other in a relaxed and informal setting.
PyDataBCN is a free non-profit event and is open to everyone, regardless of their level of experience or background. We encourage students, professionals, and enthusiasts to join us and become part of the vibrant and growing community of data scientists and engineers in Barcelona.
We look forward to seeing you at PyDataBCN and sharing our passion for Python, data science, and engineering!
PyDataBCN would like to expressly clarify that it is an independent event and is not associated or affiliated with the PyData events organized by NumFOCUS. PyDataBCN operates autonomously with its own distinct goals, structure, and organization.
Important dates
11th April: Call for proposals opening 10th May: Call for proposals closing 24th May: Program available 26th May,10AM: Early registration open for speakers, sponsors and PyLadiesBCN members 29th May, 9AM: General registration open through Eventbrite 10th June: PyDataBCN 2023
Registration
General registration will open on Monday 29th of May, at 9AM through Eventbrite.
Juan Luis Cano Rodríguez
Sala d'actes Ada Lovelace
Language: Spanish Topic: (Maintainable) Data Science Python level: Intermediate Topic level: Beginner
Convierte tus notebooks de Jupyter en código mantenible con Kedro
Juan Luis Cano Rodríguez
Sala d'actes Ada Lovelace Language: Spanish Topic: (Maintainable) Data Science Python level: Intermediate Topic level: Beginner
Los notebooks han sido fundamentales para el surgimiento de la ciencia de datos como campo, ya que brindan una interfaz fácil de usar, ofrecen un feedback rápido, y constituyen tanto un entorno de desarrollo como un formato de intercambio. Sin embargo, también se reconoce ampliamente que a menudo plantean problemas de reproducibilidad y mantenibilidad: el 90 % de los notebooks de Jupyter publicados no indican explícitamente las dependencias de los paquetes (Wang et al, 2021), y el 96 % de ellos contener errores o estado oculto que impidió obtener los mismos resultados después de volver a ejecutar (Pimentel et al, 2019). Se han propuesto varias herramientas y enfoques para mitigar los problemas de los notebooks para datos de producción. ciencia. En este taller, los autores proponen un flujo de trabajo que consiste en la refactorización iterativa de notebooks de Jupyter: mediante la extracción incremental de referencias de datos y lógica de negocio en módulos reutilizables de Python, los participantes serán capaces de explotar las capacidades dinámicas de los notebooks manteniendo su complejidad bajo control. Estos módulos de Python harán uso de Kedro, un framework Python para crear pipelines de datos reproducibles, mantenibles y modulares.
Requirements:
Experiencia con Python, conocimiento básico de Jupyter y pandas
Amalia Vradi
Aula Hedy Lamarr
Language: English Topic: Data Analysis Python level: Beginner Topic level: Beginner
Jupyter Notebooks 101
Amalia Vradi
Aula Hedy Lamarr Language: English Topic: Data Analysis Python level: Beginner Topic level: Beginner
This will be an interactive workshop on Jupyter Notebooks, the popular web application that enables you to create and share documents that contain live code, equations, visualizations and narrative text. In this beginner-friendly session, you’ll discover what Jupyter Notebooks are and what you can do with them. We’ll also introduce you to Google Colab and Kaggle, two platforms that offer free, cloud-based versions of Notebooks. You’ll get hands-on experience with installing and using them, as well as experimenting with the features offered by the platforms. Bring your laptop and your curiosity and learn how to take your data science projects to the next level using Jupyter Notebooks!
Fiorella Piriz Sapio
Sala Margarita Salas
Language: Spanish Topic: Big Data Analysis Python level: Intermediate Topic level: Intermediate
Data orchestration with Airflow
Fiorella Piriz Sapio
Sala Margarita Salas Language: Spanish Topic: Big Data Analysis Python level: Intermediate Topic level: Intermediate
Introduction to the Python-based data orchestration tool, Airflow. We will learn about airflow components and create the first Dags using some of its main operators and connectors. Finally, we will learn how to connect Airflow with Kubernetes and Spark.
Comenzaremos con un conjunto de datos de imágenes sin procesar, entrenaremos un modelo de aprendizaje automático usando fastai/PyTorch y crearemos una aplicación web con FastAPI para permitir que los usuarios interactúen con el modelo.
Juan Bernardo Lince
Sala d'actes Ada Lovelace
Language: English Topic: Data Analysis Python level: Beginner Topic level: Beginner
Data Analytics with Python
Juan Bernardo Lince
Sala d'actes Ada Lovelace Language: English Topic: Data Analysis Python level: Beginner Topic level: Beginner
Introduction to Data Analytics with Python and Pandas, building a parallel with Excel on how to create columns, summarize information and retrieve quick statistics. Questions, such as “how can we process data with code?” and “which issues should I be addressing with data?” will be explored, through guided examples on a dataset, to answer business inquiries.
In the second part, examples on Pandas built-in quick plots will be provided. Additionally, we will use Seaborn to create charts and other visual information that enable us to show the answers from the analysis, in a clear and objective manner.
Amalia Vradi
Aula Hedy Lamarr
Language: English Topic: Deep Learning, Artificial Intelligence Python level: Beginner Topic level: Beginner
Train Your Own Image Classification Model in Minutes
Amalia Vradi
Aula Hedy Lamarr Language: English Topic: Deep Learning, Artificial Intelligence Python level: Beginner Topic level: Beginner
Learn how to train your own image classification model with fastai in this hands-on workshop. You’ll discover how easy it is to build a custom model to classify any type of image you want, without needing any special hardware or software. We’ll use Google Colab and Kaggle’s free GPU instances to train our models, so all you need is your laptop and a curious mindset. Join us to explore the exciting world of computer vision!
Requirements:
A google account (to be able to use Google Colab) or a Kaggle account, for using free GPU instances
Daniel Sánchez Santolaya
Sala Margarita Salas
Language: English Topic: Machine Learning Robustness and Monitoring Python level: Intermediate Topic level: Intermediate
Machine Learning Robustness and Monitoring
Daniel Sánchez Santolaya
Sala Margarita Salas Language: English Topic: Machine Learning Robustness and Monitoring Python level: Intermediate Topic level: Intermediate
Mercury is a python library used in BBVA in data science projects. Recently, we open-sourced some parts of the library to the python and data science community.
In this workshop, we will introduce mercury.robust and mercury.monitoring. With mercury.robust we can perform dataset and model testing to detect undesirable conditions such as high level of noise in the labels, label leaking in the features of the dataset, or model excessive sensitivity to drift in certain features. Mercury.monitoring includes components that can help us detect data drift in our inference data and estimate the performance of our model when real labels are not available yet.
During the workshop we will use components of these libraries during different phases of a machine learning project: dataset generation, model training, and model inference.
The workshop is intended for data scientists and machine learning engineers interested in tools that can help improve the robustness and performance degradation detection of their machine learning models.
Requirements:
Laptop with python installed (or alternatively laptop with access to Google Colab can be used as well)
Muchas bases de datos utilizan índices invertidos para permitir realizar búsquedas de texto completo (full-text search). Veremos cómo funciona un índice invertido y crearemos uno desde cero. También aprenderemos a clasificar los resultados de una búsqueda implementando TF-IDF.
Requirements:
Conocimiento de elementos de Python como funciones, clases, bucles, comprensiones de listas, generadores, etc. Conocer las estructuras de datos principales de Python (listas, sets, tuples, diccionarios…). Habilidades básicas de procesamiento de texto (manipular cadenas de texto y conocimiento básico de expresiones regulares (regex)). Para el taller solamente utilizaremos la librería estándar de Python. Se recomienda usar Python 3.7 o superior.
Ruben Afonso
Sala d'actes Ada Lovelace
Language: English Topic: Artificial Intelligence Python level: Intermediate Topic level: Beginner
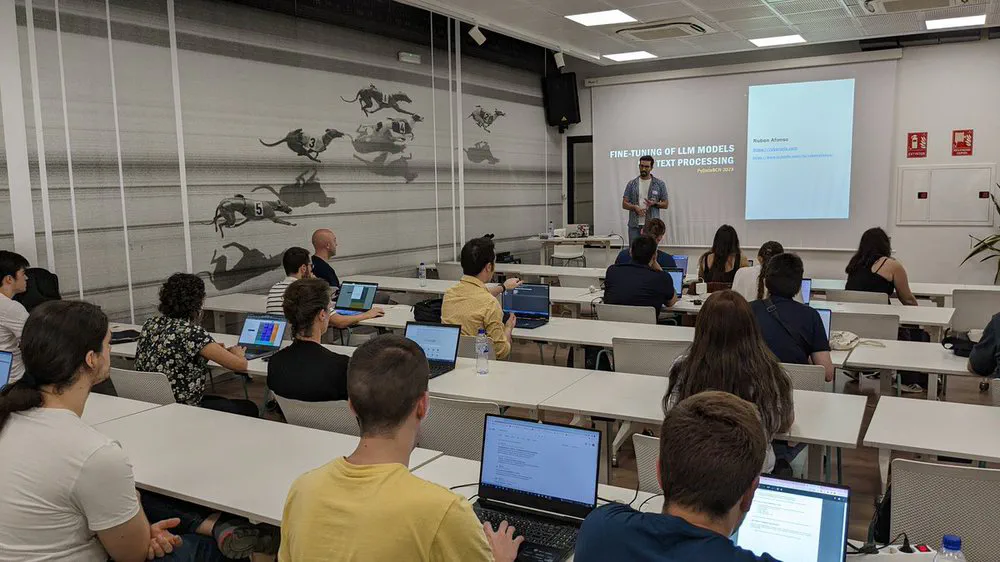
Fine-tuning of LLM models for text processing
Ruben Afonso
Sala d'actes Ada Lovelace Language: English Topic: Artificial Intelligence Python level: Intermediate Topic level: Beginner
In this workshop we will review how to leverage your Python skills to reuse and fine-tune some of the latest Generative LLM (Large Language Models) available and strategies to tackle specific use cases such as text summarisation and question-answering
In this workshop you will learn the logic and foundations behind Machine Learning, to better understand how it can be used and where not to. The Different use cases of Machine Learning, and practical exercises of the most typical Machine Learning tasks: regression and classification. Finally how to predict the gender pay gap based on some features such as job descriptions, age and other demographics.
Carmen Iniesta López
Sala Margarita Salas
Language: English Topic: Machine Learning, NLP, Semantic search, Generative AI Python level: Intermediate Topic level: Intermediate
Ask your data! Build a full pipeline to get generative answers from a text dataset
Carmen Iniesta López
Sala Margarita Salas Language: English Topic: Machine Learning, NLP, Semantic search, Generative AI Python level: Intermediate Topic level: Intermediate
The goal of this workshop is to teach attendees how to build a full pipeline to generate sentence embeddings from a given dataset, index them in a vector database for semantic search, and integrate search results as context for a LLM.
Requirements:
Intermediate knowledge of Python programming, understanding of natural language processing and semantic search concepts, enthusiasm and willingness to learn and collaborate. Technical requirements: Laptop with python >= 3.9 installed and HF’s SentenceTransformers. Nucliadb is optional, if not installed we’ll do it together during the workshop. A requirements.txt and more details will be provided prior to the event.
Aprèn a visualitzar paràmetres i prediccions de models probabilístics emprant histogrames, estimadors nuclears de densitat (KDE), gràfics de punts per quantils i funcions de distribució empíriques
Requirements:
Cal certa comoditat a l’hora de treballar amb Python, NumPy i Matplotlib. Tots els gràfics seran introduïts abans d’utilitzar-se, però és recomanable tenir coneixements bàsics d’estadística.
Adrián García Riber, Albert Pujol Torras, Álvaro Durán Barata, Diego Quintana, Edgar Sarria Tenes, Miquel Sàrrias, Monica Dominguez, Rajdeep Pal, Ricardo Ander-Egg Aguilar, Sergi Baena-Miret and Thais Ruiz de Alda
Sala d'actes Ada Lovelace
Language: English / Spanish Topic: Multiple topics
Lightning talks session
Adrián García Riber, Albert Pujol Torras, Álvaro Durán Barata, Diego Quintana, Edgar Sarria Tenes, Miquel Sàrrias, Monica Dominguez, Rajdeep Pal, Ricardo Ander-Egg Aguilar, Sergi Baena-Miret and Thais Ruiz de Alda
Sala d'actes Ada Lovelace Language: English / Spanish Topic: Multiple topics
How Data Scientists Can Be More Productive with the Power of Static Typing - Alvaro Duran Data scientists frequently find themselves in situations where they need to verify that some intermediate step in a data pipeline works as expected, and tools such as Jupiter notebooks, where each step is explicitly shown to the user, are very useful at that. However, it can become quite cumbersome and time-consuming as the data pipeline grows more complex. That's where static typing comes in. By using types in our code, we can introduce our data into a structured pipeline and catch errors early on, before they have the chance to cause any real problems. This is particularly useful when working with large datasets, where a small error can have a significant impact on our results. But what exactly do we mean by 'types'? Essentially, types are a way of specifying the kind of data that a variable or function will handle. For example, we might specify that a certain variable should only contain integers, or that a certain function should only accept strings. By using types, we can catch errors early on in the development process, rather than having to wait until runtime to discover them. This can save us a lot of time and effort in the long run, as we can catch errors before they have a chance to cause any real damage. Now, you might be thinking, 'but doesn't introducing types make our code more complex?' And the answer is, not necessarily. In fact, Python has built-in support for types that makes it easy to incorporate them into our code. Of course, that is just the first part of the puzzle. Good type systems are analogous to test suites: they require some effort, but the payoff is immense. This talk will cover the very basics of how data scientists can benefit from using types, not only on their production code, but even on crude prototypes, giving some peace of mind by making illegal states unrepresentable.
Astronomical data Sonification - Adrián García Riber The current development of massive astronomical archives and virtual observatory technology (VO) offers a wide range of data products and services that can be explored with a personal computer through interoperable technology. The use of sonification and musification in multimodal displays for the exploration of astronomical data offers an additional domain (complementary to visualization), that allows researchers to get immersed in their case studies, navigating the massive downloads of big data generated by space telescopes, and that makes stellar catalogs and databases more accessible for blind-visually impaired (BVI) users. In this talk I would like to introduce the collection of Python and TensorFlow Sonification prototypes developed in my PhD to generate multimodal representations of astronomical data using Deep Learning and Neural Networks.
Python models and alerts within dbt with dbt-fal and novu - Diego Quintana How to trigger alarms and run python models within dbt with dbt-fal and novu. dbt is the T in the ELT pipe. Although dbt allows for python model since version 1.3, its support is limited. dbt-fal enables running python models and python code in general within a model. A simple demo will be shown, with a forecasting model is trained as part of a dbt pipeline and an alarm is triggered with novu, an open source notification infrastructure.
Serverless Machine Learning: Streamlining Deployment and Scaling of ML Services - Rajdeep Pal The topic of deploying machine learning services using a serverless architecture is focused on leveraging cloud computing services to simplify the deployment and scaling of machine learning models. Using a serverless approach, developers can focus on writing code for their ML models without worrying about infrastructure setup and management. The serverless model also provides automatic scaling of resources to meet the demands of incoming requests, reducing the need for manual intervention and ensuring that services remain highly available. This talk would cover the benefits of using a serverless approach to deploy machine learning services and provide practical guidance on how to implement it effectively. It would also explore the challenges and trade-offs involved in using serverless architecture for ML services, such as performance considerations, security, and cost optimisation.
Practical considerations when using chatGPT in production for multilanguage processing - Albert Pujol Torras We will describe the results of empirical measurements of the behavior of LLMs to automate NLP processes depending on both the language in which the prompt is written, the lenguage of the text to be analyzed as well as some practical considerations to take into account when considering putting in production this type of Models.
International Data Spaces: Implementing the European Strategy on Data - Miquel Sarrias The International Data Spaces (IDS) initiative aims at cross-sectoral data sovereignty and data interoperability. It sets forth a Reference Architecture Model basing on open standards and contributing to global standards. By specifying data usage constraints, it defines the terms and conditions for the data economy. Data spaces are key to the global, digital economy. The European Commission is defining Europe's path forward into the digital economy of the future. A core element of their vision: international data spaces grounded in European values of trust and the self-determination of data usage by data providers, that we call data sovereignty.
Forecasting in the integral water cycle - Sergi Baena-Miret Droughts can have severe impacts on water availability, demand, and quality, affecting water allocation, infrastructure planning, and environmental protection. Accurate forecasting of droughts is essential for mitigating their impacts by enabling effective water management strategies. Various techniques such as statistical models, machine learning, and remote sensing are used for drought forecasting in the integral water cycle. However, challenges such as data scarcity, non-stationarity, and uncertainty in climate change projections pose significant challenges for accurate forecasting.
MusicMetaData & algorithmic diversity perrspective - Thais Ruiz de Alda We want to talk about the current challenge de music industry is facing around metadata and the challenges that including a gender perspective can imply. The talk will cover the story of music metadata and how Digitalfems is challenging the musical descriptive metadata status quo to develop an ADM system that will include gender diversity in a beta testing/lab environment with the support of different institutions such as FECYT, UPC and other relevant stakeholders
Free online Data Apps with Shimoku Library - Edgar Sarria We will show how to use Shimoku instead of Streamlit to build Data Products in few lines of code
Data Science in Transport Modelling - Monica Dominguez Transport modelling and traffic simulation have traditionally been branches of Civil Engineering and Applied Mathematics. In this talk, we will present how the field is embracing Data Science and Machine Learning methodologies for data processing, pattern analysis, forecasting and prediction of recurrent and non-recurrent events.
Bundling a Python app in a single file - Ricardo Ander-Egg Live coding talk. This talk will show how to bundle a Python app and all of its dependencies in a single file. Then we will copy this file to a different machine and see how the script runs without having to deal with Docker or virtual environments.
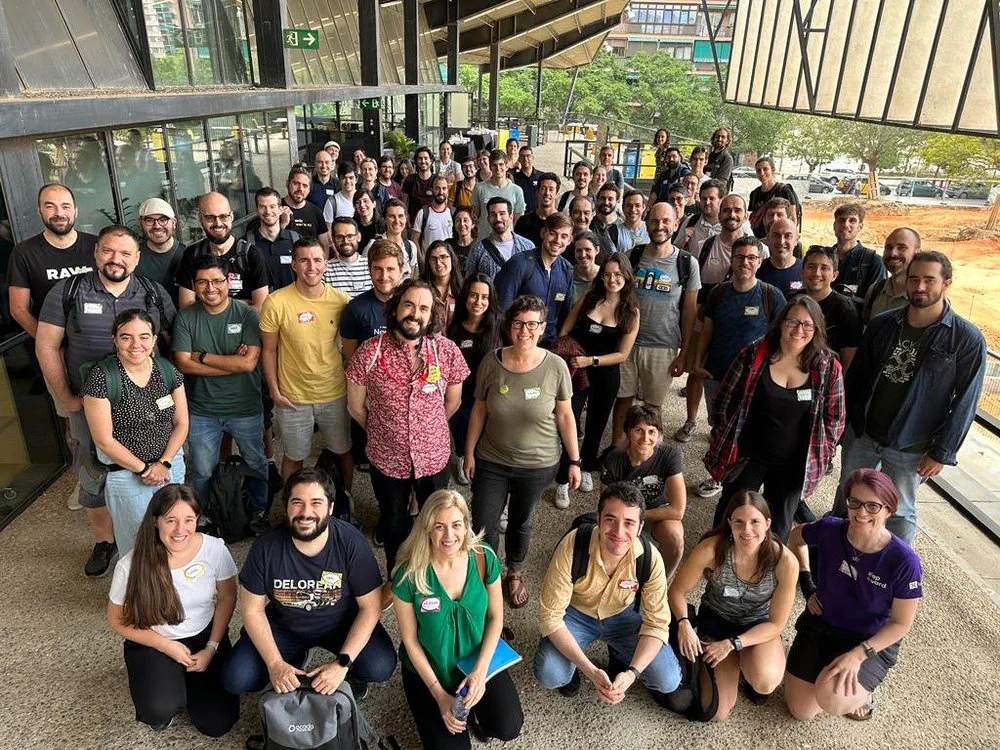
The PyDataBCN 2023 has been incredible! We are grateful for all the organizers, volunteers, speakers, sponsors and assistants. See you at our next event!